



An image generation LLM turns a written description into a finished picture. For food and beverage teams, that changes what a concept costs to see. A packaging idea, a plated dish or a shelf scenario can exist as an image in the time it takes to write two sentences.
The technology is mainstream rather than experimental. EMARKETER forecasts 133 million generative AI users in the United States in 2026, close to 2 in 5 people. This guide covers how the rendering works, which models lead today, and where generated visuals earn their place in product and marketing work.
Key takeaways
- An image generation LLM weights every word you give it, so a prompt has to state what to include. Asking for fries without ketchup still returns ketchup.
- Model choice follows the job. GPT Image 2 leads on prompt accuracy, Midjourney V8.1 on art direction, FLUX.2 Pro on high volume rendering through an API.
- For CPG innovation teams, the value is speed to a visual. A packaging concept for a 20g protein bar can be rendered on shelf before anyone books a photographer.
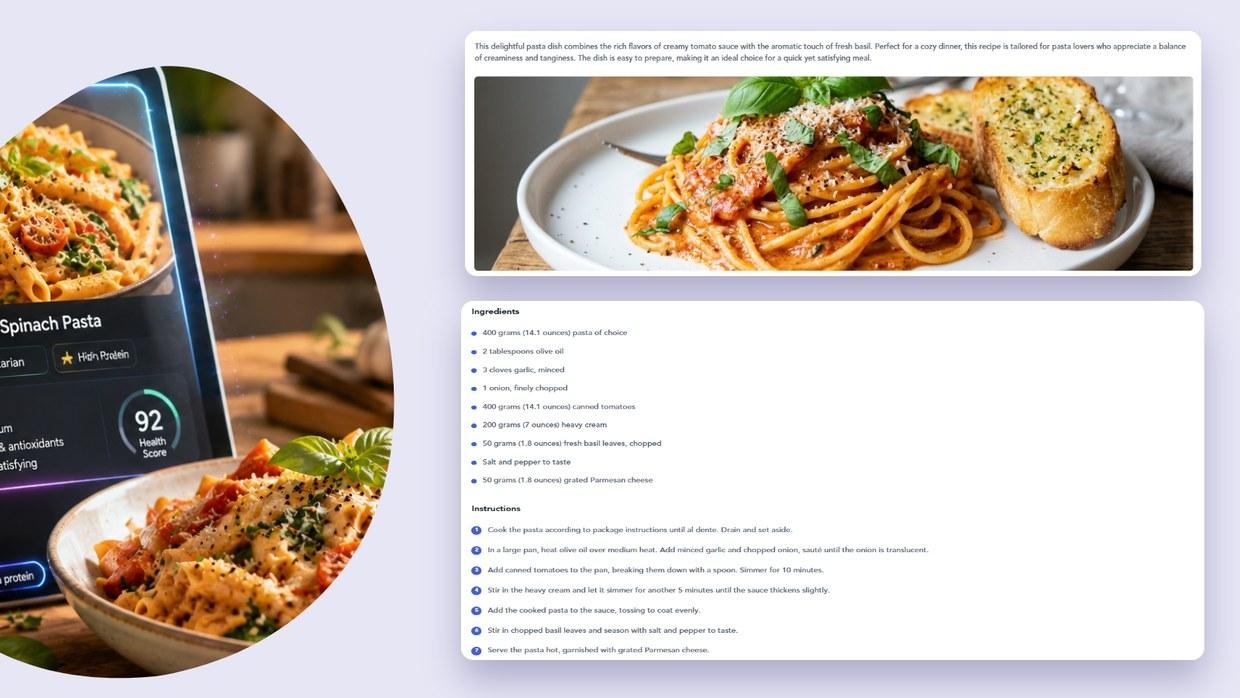
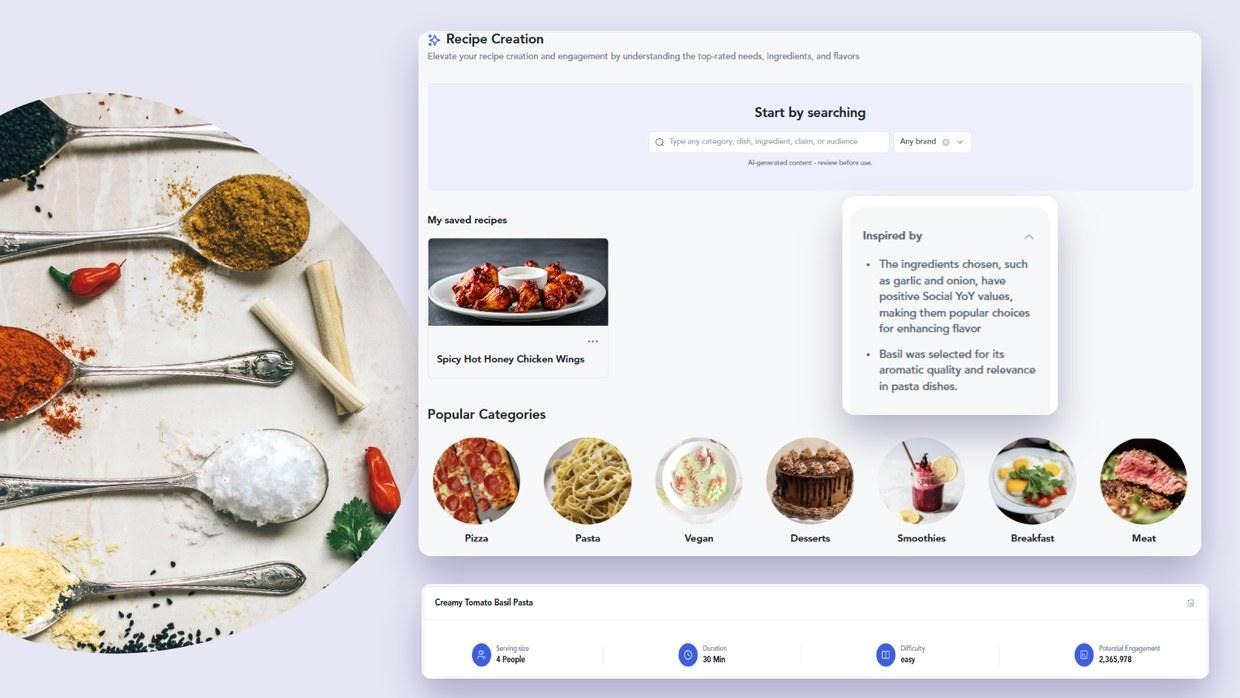
- For culinary and menu teams, the AI Recipe Agent turns a dish idea into a plated visual and a build, so an LTO concept gets reviewed in a meeting rather than a test kitchen.
- A generated visual carries more weight when the same platform can show that the flavor behind it is climbing on menus and shelves.
- The image is one step in a longer job. The agent library covers concept, audience, proof and asset in one system, so a visual arrives attached to the evidence for it.
What an image generation LLM actually is
LLM stands for large language model, a system trained to predict text. On its own it writes rather than draws. What people call an image generation LLM is a multimodal system where language understanding and image rendering sit together, so a sentence you type becomes the instruction set for a picture.
The distinction matters commercially. The language half decides whether the model grasps that a ramp bagel is a bagel flavored with ramps. The rendering half decides whether the crumb, the glaze and the plating look like food someone would eat.
How LLMs generate images
Two routes are in use, and they behave differently under pressure.
In the older pipeline, a text model reads your prompt and rewrites it as a structured description. It passes that description to a diffusion model, which resolves random noise into pixels over many steps. Each handoff is a place where intent can be lost.
In the newer native multimodal route, one model predicts image tokens alongside text tokens. The same weights that read the prompt also render the picture, so the instruction and the output never separate. Native rendering is why current models handle a phrase like without ketchup far more reliably than the 2024 versions did.
Why prompt precision decides the output
Image generation LLMs give weight to each word rather than reading a sentence the way you do. A negative instruction is the clearest example. Ask for french fries without ketchup and older models put ketchup in the frame, because the phrase told them what to exclude and the word ketchup still carried weight.
Ambiguity produces the same problem in a quieter way. A prompt reading ramp bagel, plated leaves the model to guess whether the ramps belong in the dough or the filling. One test returned two plain bagels and two bagel sandwiches from the same instruction.
Adding white chocolate to a cookie splits four ways. The model needs to know whether the white chocolate flavors the dough, sits on top as a drizzle, fills the center, or runs through the cookie as chunks. Each of those is a different product on a shelf.
The fix is to let a language model expand your intent into an unambiguous instruction before it reaches the renderer. Name the format, the finish, the plating and the camera distance. Precision at the prompt stage is cheaper than a reshoot.
Choosing an LLM for image generation
There is no single winner, so the answer depends on the job in front of you.
- GPT Image 2 leads on prompt accuracy and conversational editing, which suits iterative packaging work.
- Midjourney V8.1 leads on art direction and stylized food photography, which suits moodboards and campaign concepts.
- Nano Banana Pro and FLUX.2 Pro are the usual picks for high volume marketing imagery through an API.
Four features separate a strong image generator LLM from a demo. Prompt adherence, so the brief survives the render. Readable text rendering, so a front-of-pack claim comes back spelled correctly. Consistency across a set, so eight SKUs look like one range. Licensing terms you can put in front of a legal team before a consumer marketing campaign ships.
What a product visualizer does for CPG innovation teams
Tastewise Product Visualizer applies this to packaging. You name the product, add a short description, pick your brand, and optionally set a product type and a target audience. It returns a set of packaging concepts already rendered in context.
A protein bar entered with no other detail comes back as wrappers sitting on a retail shelf and on a wood counter, complete with front-of-pack cues the model invented for you. A 20g high protein flash. A chocolate peanut butter flavor line. Sub-brand names in the vein of Peak Performance and Peak Fuel, each on a different color route.
That output has a specific job. It gives a product innovation team something to react to in the first meeting rather than the fourth. It gives a category manager a visual to put in a range review deck. It gives you four routes to put through concept testing before any design retainer is committed.
[Image placement: Product Visualizer protein bar screenshot. Alt text: Tastewise Product Visualizer generating four protein bar packaging concepts.]
What an AI recipe agent does for culinary and menu teams
Menu work has the same bottleneck in a different form. A chef can describe a hot honey glazed chicken sandwich or a chili crisp breakfast bowl in one line, and still wait a week for a test kitchen slot before anyone sees it.
The AI Recipe Agent closes that gap. A dish idea returns as a build and a plated visual together, so the concept gets discussed on its merits in the room. The kitchen time then goes to the two ideas worth cooking instead of the eight worth sketching.
Limitations of LLM Image Generation
Although LLM image generation has many advantages, there are also some limitations to consider:
- Limited creativity: While LLM algorithms can produce realistic-looking images, they may lack the creativity and artistry that human photographers possess. This could result in generic or repetitive images.
- Lack of customization: With LLM-generated images, businesses have limited control over specific details such as plating, garnishes, and backgrounds. This could be an issue for brands with a distinct aesthetic.
- Ethical concerns: The use of AI technology raises ethical questions surrounding ownership and copyright. As more businesses turn to LLM image generation, it is essential to consider the implications and potential consequences of using AI-generated content.
Where image generation sits in an end to end agent platform
A rendered image answers what the product could look like. It says nothing about whether anyone wants it. That second question is where a visual either earns budget or stalls.
Running both in one place is the point of an agentic AI platform. The same system that renders the pack can show you which flavors are climbing on menus, which audience the concept fits, and what the campaign around it should say. The visual then travels with the evidence for it, which is what a retail buyer or an operator actually needs to see.
Frequently asked questions about image generation LLM
There is no single winner, so the answer depends on the job. GPT Image 2 leads on prompt accuracy and conversational editing, Midjourney V8.1 leads on art direction and stylized food photography, and Nano Banana Pro and FLUX.2 Pro are the usual picks for high-volume marketing imagery through an API. For commercial work, the features that make a strong image generator LLM are prompt adherence, readable text rendering, and consistency across a set of assets. A consumer marketing team shipping campaign visuals every week should also check the licensing terms before standardizing on one model.
Snack prompts tend to cluster around whatever is climbing on shelves and menus. High-protein bites, clean-label energy balls and thick-cut artisanal chips all come up constantly for image generation LLMs, partly because their surface texture is satisfying to render. Check the live food trend tracker before you brief a batch of visuals, so the snack you render is the one people are actually reaching for.
An LLM image generator has no appetite of its own. In prompt terms it performs best on visually rich, high-contrast subjects like a gourmet smash burger, a functional soda with condensation on the can, or a laminated pastry with visible layers. Those subjects give the model texture, depth and edge detail to work with, which is why they show up in so many test prompts and in AI Recipe Agent outputs.
Two routes are in use. In the older pipeline, a text model reads your prompt and rewrites it as a structured description, then passes that description to a diffusion model that resolves random noise into pixels over many steps. In the newer native multimodal route, one model predicts image tokens alongside text tokens, so the same weights that read the prompt also render the picture. Native rendering is the reason current models handle an instruction like “without ketchup” far more reliably than the 2024 versions did. The same pipeline sits behind the visuals in product innovation work, where a concept needs a picture before it reaches a buyer.

We’d love to learn your goals and see how Tastewise fits
We’d love to learn your goals and see how Tastewise fits
Get a personalized demo
Good taste. Wise move.
Your demo request is confirmed. We’ll reach out within one business day to schedule your walkthrough.
What happens next

See what’s driving demand, then turn it into a sell-in story for retailers and operators.
- Connect consumer panels, market trackers, and agents into one evidence view
- Get the “why” behind what’s changing, with explainable demand drivers
- Walk away with a buyer-ready narrative and next steps to activate
Trusted by


“Tastewise is my secret tool for knowing what consumers want next and why.“